September 22, 2026
The Production AI Observability Playbook: Instrumenting LLM Applications with OpenTelemetry
The Production AI Observability Playbook: Instrumenting LLM Applications with OpenTelemetry A production AI application can return a technically successful response and still fail the user. The model may have used the wrong retrieved documents, called an expensive tool unnecessar...
The Production AI Observability Playbook: Instrumenting LLM Applications with OpenTelemetry
A production AI application can return a technically successful response and still fail the user.
The model may have used the wrong retrieved documents, called an expensive tool unnecessarily, exceeded a latency budget, leaked sensitive context into logs, or produced an answer that looked convincing but was factually incorrect. Traditional application monitoring rarely provides enough detail to explain why.
That is the missing layer in production AI: visibility into the complete chain of events behind an AI response.
OpenTelemetry provides a vendor-neutral foundation for collecting that evidence. With the right instrumentation strategy, teams can trace requests across prompts, model calls, retrieval systems, tools, agents, and evaluations without tying their architecture to one observability vendor.
This guide explains how to design LLM observability with OpenTelemetry, what to capture, how to protect sensitive data, and how to turn telemetry into operational improvements.
Why Traditional Monitoring Breaks Down for LLM Applications
Conventional web applications are usually evaluated through familiar signals:
- Request latency
- HTTP status codes
- Error rates
- CPU and memory usage
- Database performance
- Queue depth
These metrics remain valuable for AI systems, but they do not explain the behavior of the model itself.
A single user request may pass through this sequence:
- An API gateway receives the request.
- A policy layer checks identity and permissions.
- A prompt template is assembled.
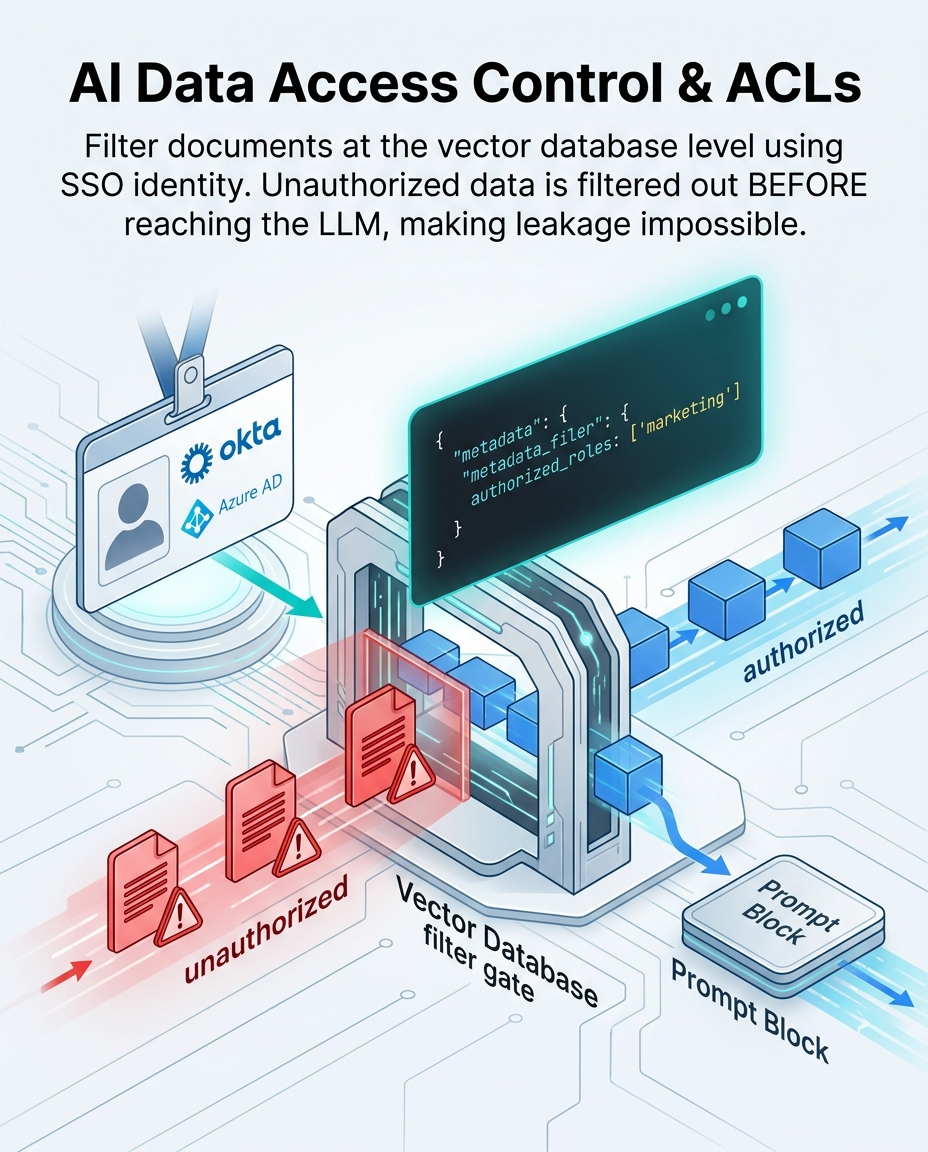
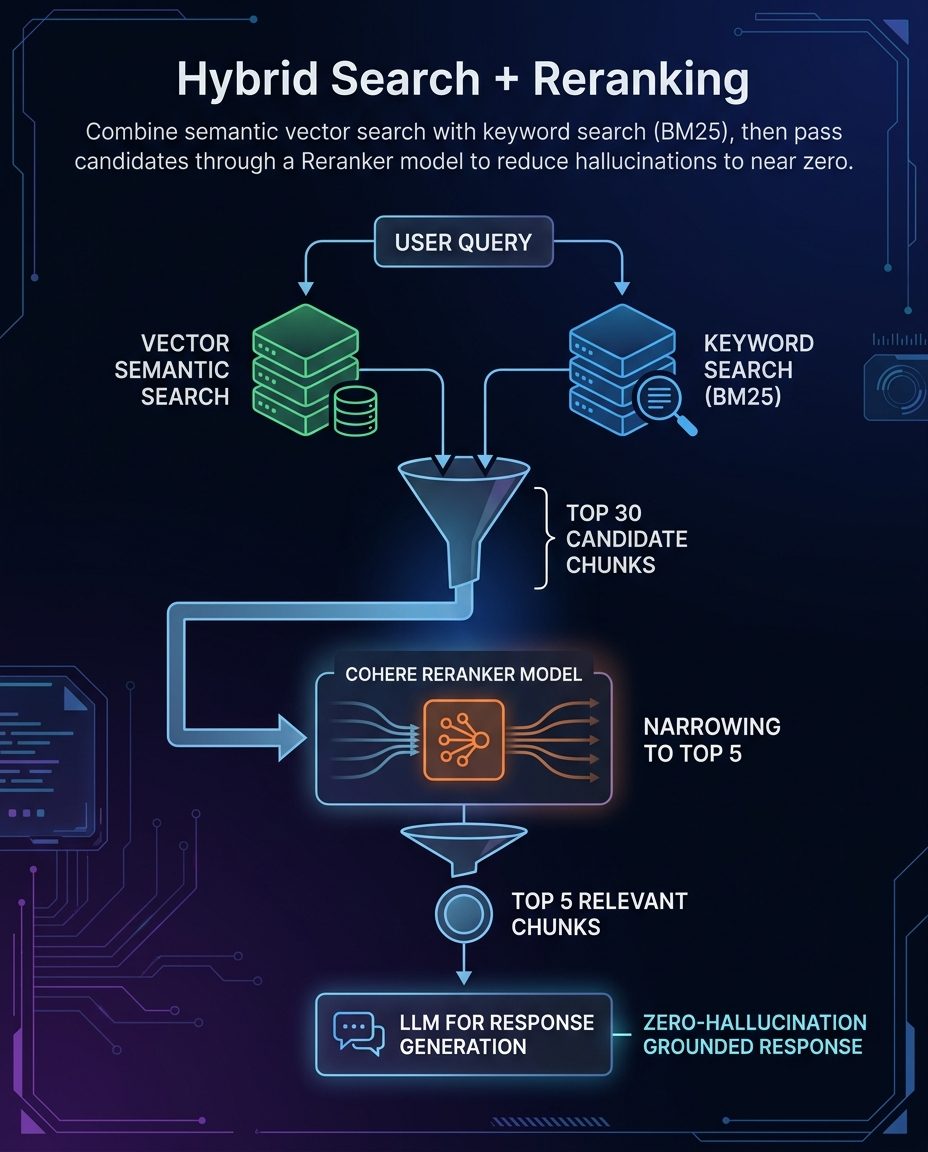
- A retrieval system searches a vector database.
- A reranker selects relevant passages.
- An LLM generates a tool call or response.
- An external API executes the tool request.
- A second model call synthesizes the final answer.
- An evaluator scores the response.
- The result is streamed back to the user.
If all you record is a 200 OK response and total duration, you cannot answer important operational questions:
- Which model call caused the delay?
- Did retrieval return useful documents?
- How many tokens were consumed?
- Was the prompt unexpectedly large?
- Did the agent enter a loop?
- Which tool failed?
- Did a model fallback change the response quality?
- Was the final answer grounded in retrieved evidence?
- Did the request expose private customer data?
OpenTelemetry addresses this by connecting the entire workflow through correlated traces, metrics, and logs.
Key insight: For LLM applications, the unit of observability is not the HTTP request alone. It is the full execution trace that explains how an input became an output.
The Core Model: Traces, Metrics, Logs, and Events
OpenTelemetry is built around several complementary telemetry signals. The most effective LLM monitoring strategy uses all of them, but assigns each signal a specific job.
Traces explain execution
A trace represents one end-to-end operation. In an AI application, the root span might represent a user request, with child spans for each meaningful stage:
- Request handling
- Prompt construction
- Retrieval
- Reranking
- Model invocation
- Tool execution
- Guardrail checks
- Response evaluation
A model call span should ideally include metadata such as:
- Provider
- Model name
- Input and output token counts
- Request duration
- Finish reason
- Temperature or equivalent sampling settings
- Response status
- Retry count
- Fallback usage
- Prompt and completion identifiers
Avoid treating every internal function as a span. Instrument operations that help explain latency, cost, quality, or failure. Excessive span volume increases storage costs and makes traces harder to interpret.
Metrics reveal aggregate behavior
Metrics help answer questions across thousands or millions of requests:
- P50, P95, and P99 latency
- Requests per model
- Error rate by provider
- Input and output tokens
- Estimated cost
- Tool-call frequency
- Retrieval result counts
- Guardrail rejection rate
- Evaluation scores
- Agent iteration count
- Fallback rate
A trace can explain one slow request. A metric can reveal that a specific model has become slow for an entire region or that a new prompt version has doubled token usage.
Logs provide detailed diagnostic context
Logs are useful for exceptions, policy decisions, configuration changes, and lifecycle events. They should be correlated with trace and span IDs so an operator can move from a dashboard to the exact execution path.
Do not use logs as a substitute for structured tracing. A large text log containing an entire prompt and response may be difficult to search, expensive to retain, and dangerous from a privacy perspective.
Span events capture meaningful moments
Some details do not need their own span but still matter. Span events can record:
- Retrieval completed
- Safety filter triggered
- Tool approval requested
- Retry initiated
- Human review assigned
- Streaming completed
- Evaluation threshold failed
This keeps traces readable while preserving important execution milestones.
Designing an LLM Telemetry Schema
OpenTelemetry provides the transport and data model, but your team still needs a consistent semantic design.
The key is to define a small set of stable attributes that can be queried across applications. OpenTelemetry GenAI semantic conventions are evolving, so review the current specification and document which fields your organization treats as stable. Do not assume that every experimental attribute will remain unchanged.
A practical span taxonomy might look like this:
| Span kind | Example operation | Useful attributes |
|---|---|---|
| Server | chat.request | Route, tenant, user-safe request ID |
| Internal | prompt.build | Template version, prompt category |
| Client | llm.generate | Provider, model, token counts, finish reason |
| Internal | retrieval.search | Index, top-k, result count, filter policy |
| Client | tool.execute | Tool name, status, duration, approval state |
| Internal | evaluation.score | Evaluator version, score, threshold result |
Use names that describe the operation rather than the implementation. For example, llm.generate remains useful if the provider changes from one API to another.
What belongs in attributes
Attributes should support filtering, grouping, and aggregation. Good examples include:
ai.providerai.modelai.operationai.prompt_versionai.applicationai.environmentai.tenant_tierai.tool.nameai.retrieval.top_kai.retrieval.result_countai.evaluation.status
Keep high-cardinality data under control. A raw user ID, full prompt, or unique conversation identifier can create expensive and inefficient metric dimensions. Put such values in trace context only when there is a clear operational need and a strong privacy model.
What should not be captured by default
Avoid automatically storing:
- Full user prompts
- Full model responses
- Access tokens
- API keys
- Passwords
- Payment information
- Health information
- Private documents
- Unredacted tool arguments
A safer design records hashes, classifications, redacted excerpts, or references to separately controlled encrypted storage.
Telemetry should be observable by design, not indiscriminate by default. The goal is to preserve enough evidence to debug behavior without turning your observability platform into a second data lake of sensitive content.
A Step-by-Step OpenTelemetry Implementation
Step 1: Establish the root trace
Begin at the public entry point, such as an HTTP endpoint, queue consumer, or workflow trigger. The root span should carry the request through the entire AI execution.
Use standard OpenTelemetry SDKs for your language and framework. Propagate context across:
- HTTP requests
- Asynchronous jobs
- Message queues
- Agent handoffs
- Tool calls
- Service-to-service requests
Without context propagation, the model call may appear as an unrelated event instead of part of the user’s request.
Step 2: Add spans around model calls
Wrap every provider request with a client span. Record operational metadata even when content capture is disabled.
A simplified Python example might look like this:
from opentelemetry import trace

tracer = trace.get_tracer("support-assistant")

def generate_answer(messages, model_client, model_name):
    with tracer.start_as_current_span("llm.generate") as span:
        span.set_attribute("ai.operation", "chat")
        span.set_attribute("ai.provider", model_client.provider)
        span.set_attribute("ai.model", model_name)

        response = model_client.generate(
            model=model_name,
            messages=messages
        )

        usage = getattr(response, "usage", None)

        if usage:
            span.set_attribute("ai.input_tokens", usage.input_tokens)
            span.set_attribute("ai.output_tokens", usage.output_tokens)

        span.set_attribute(
            "ai.finish_reason",
            getattr(response, "finish_reason", "unknown")
        )

        return response
In production code, add error recording and status handling:
try:
    response = model_client.generate(model=model_name, messages=messages)
    span.set_status(StatusCode.OK)
    return response
except Exception as exc:
    span.record_exception(exc)
    span.set_status(StatusCode.ERROR, str(exc))
    raise
The exact implementation varies by framework and provider. The principle remains consistent: every model invocation should be traceable, measurable, and associated with the parent request.
Step 3: Instrument retrieval and reranking
Retrieval quality is often the hidden cause of poor AI responses. Add spans for:
- Query rewriting
- Embedding generation
- Vector search
- Metadata filtering
- Reranking
- Context assembly
Useful measurements include:
- Search duration
- Number of candidates
- Number of final passages
- Similarity score distribution
- Index or collection name
- Filter policy
- Empty-result rate
- Maximum context size
Do not record private document contents in ordinary telemetry. Instead, use document identifiers, source classifications, content hashes, or secure references that authorized reviewers can resolve separately.
Step 4: Trace tools and agent decisions
Tool calls need their own spans because they introduce external latency, failure modes, and security risks.
Capture:
- Tool name
- Input schema version
- Approval requirement
- Start and completion time
- Success or failure
- Retry count
- Result classification
- Timeout status
For agentic systems, also record bounded control information:
- Current iteration number
- Maximum allowed iterations
- Planning phase
- Selected tool
- Stop reason
- Delegated agent name
- Human approval status
Avoid logging hidden reasoning or chain-of-thought content. Operational telemetry can describe decisions through structured labels such as tool_selected, policy_blocked, or max_iterations_reached without collecting private internal reasoning traces.
Step 5: Export through an OpenTelemetry Collector
A Collector provides a layer between applications and observability backends. It can receive OTLP data, process it, redact fields, sample traces, and export to one or more destinations.
A typical production path is:
- Application emits OTLP traces, metrics, and logs.
- Collector receives telemetry close to the workload.
- Processors redact sensitive fields and enrich resource metadata.
- Tail sampling keeps important traces.
- Exporters send data to approved backends.
This architecture helps avoid embedding vendor-specific exporters in every application.
Collector processors can support:
- Attribute deletion
- Attribute transformation
- PII filtering
- Resource enrichment
- Batch export
- Memory limiting
- Probabilistic sampling
- Tail-based sampling
Use tail sampling carefully. You may want to retain:
- All errors
- All guardrail violations
- All high-cost requests
- Slow traces above a latency threshold
- Traces from a controlled evaluation cohort
- A representative sample of successful requests
Production AI Monitoring: Turning Telemetry Into Action
Instrumentation has value only when it changes how teams operate.
Create dashboards around user and business outcomes, not just infrastructure health. A useful production AI monitoring dashboard might include:
Reliability
- Request success rate
- Model timeout rate
- Provider error rate
- Tool failure rate
- Retry and fallback frequency
- Agent loop termination rate
Performance
- End-to-end P50 and P95 latency
- Time to first token
- Time between streamed tokens
- Retrieval duration
- Model duration
- Tool duration
- Queue wait time
Cost
- Tokens per request
- Estimated cost by model
- Cost by feature or tenant
- Cost of retries
- Cost of fallback routing
- High-token outlier requests
Quality
- Groundedness score
- Citation or source coverage
- Human review rate
- Refusal rate
- Evaluation pass rate
- User feedback trend
- Escalation rate
Safety and governance
- Prompt injection detections
- Sensitive data events
- Policy blocks
- Unauthorized tool attempts
- Data residency violations
- Human approval bypasses
A basic alert should connect symptoms to action. For example:
- Alert when P95 latency exceeds the service objective for 15 minutes.
- Alert when model error rate exceeds the fallback threshold.
- Alert when average output tokens increase sharply after a prompt deployment.
- Alert when tool failure rate rises for one integration.
- Alert when evaluation scores fall below the release gate.
Avoid alerting on every isolated hallucination. Quality signals are often noisy. Use statistically meaningful samples, evaluation cohorts, and trend-based thresholds.
Sampling, Privacy, and Cost Controls
LLM telemetry can become expensive quickly because model inputs and outputs are large. A production design should separate operational telemetry from content-level diagnostics.
Consider a tiered retention model:
Data Retention Approach
- Core metrics: Latency, errors, token usage, and cost data. These can be retained for a longer period for monitoring, reporting, and trend analysis.
- Trace metadata: Span names, model information, status, and execution durations. Retain this data for a medium to long period to support observability and troubleshooting.
- Error traces: Failed requests, errors, and relevant policy events. These should have extended retention to support incident investigation and security analysis.
- Content samples: Redacted prompts and outputs used for debugging or quality analysis. These should have short retention periods to minimize exposure of potentially sensitive content.
- Evaluation records: Evaluation scores and references to human or automated reviews. Retention should be controlled based on evaluation requirements and governance policies.
Practical controls include:
- Sample successful traces more aggressively than failures.
- Keep complete traces for internal test environments.
- Capture content only for opted-in evaluation cohorts.
- Redact before export, not after storage.
- Encrypt sensitive diagnostic records.
- Restrict access using role-based policies.
- Record who viewed sensitive traces.
- Define deletion and retention policies before launch.
Sampling should not hide systemic failures. If a rare event has severe impact, use rule-based retention to preserve it regardless of normal sampling rates.
Building an Operational Feedback Loop
The strongest teams treat observability as part of the AI development lifecycle.
When a production trace reveals a problem, route it through a repeatable loop:
- Identify the failure pattern in telemetry.
- Extract a sanitized example.
- Add it to an evaluation dataset.
- Reproduce the behavior in a test environment.
- Change the prompt, retrieval logic, model, tool policy, or application code.
- Run the evaluation suite.
- Compare quality, latency, cost, and safety metrics.
- Deploy gradually.
- Monitor the new version against the previous baseline.
Add version identifiers to telemetry so changes remain attributable:
- Application version
- Prompt version
- Model version
- Retrieval index version
- Tool schema version
- Guardrail policy version
- Evaluator version
Without versioning, a dashboard may show that quality changed but not which release caused it.
A Practical Readiness Checklist
Before declaring an LLM application observable in production, verify that it can answer the following:
- Can an engineer trace one user request across retrieval, model calls, and tools?
- Are model, provider, prompt version, and application version recorded?
- Can the team distinguish model latency from retrieval and tool latency?
- Are token usage and estimated cost measurable?
- Are errors correlated with trace IDs?
- Are retries, fallbacks, and agent loops visible?
- Can quality evaluations be linked to the relevant execution trace?
- Are prompts, responses, and tool arguments protected from accidental exposure?
- Does the Collector redact and sample telemetry before export?
- Are dashboards organized around reliability, performance, cost, quality, and safety?
- Can a production failure become a sanitized regression test?
- Are retention, access, and deletion policies documented?
If several answers are no, the application may be monitored, but it is not yet observable.
Conclusion: Make Every AI Response Explainable
Production AI requires more than uptime monitoring. Teams need to understand the path from user intent to model output, including the context retrieved, tools invoked, policies applied, tokens consumed, and quality signals generated along the way.
OpenTelemetry supplies the connective tissue for that visibility. It allows organizations to instrument AI workflows using open standards, preserve provider flexibility, and integrate model behavior into existing engineering operations.
Start with a small scope:
- Trace the top user-facing AI endpoint.
- Instrument model, retrieval, and tool spans.
- Record safe operational metadata.
- Export through a Collector.
- Build dashboards for latency, cost, errors, and quality.
- Add privacy controls before expanding content capture.
- Turn meaningful production failures into evaluation cases.
The result is not merely better dashboards. It is a production AI system that can be investigated, governed, improved, and trusted.
Related Reading
Enjoyed this article? Join the Growency newsletter
Practical AI tips for service businesses, straight to your inbox. No spam, unsubscribe anytime.